- Use Handy with Parakeet V3 for short transcription (“Push to Talk”)
- Use Parakeet TDT Transcription with ONNX Runtime for long transcription (audio files)
Introduction
This article is about using Automatic Speech Recognition (ASR) (also known as Speech-to-Text (STT)) for transcribing English, meaning that you talk to a mic and then have it type out onto the screen. The “AI” landscape has exploded for the past few years and along with it, a lot of new ASR models that can be run locally. I have tried different models and found some good app that I think are worth recommending.
My Four Requirements/Assumptions
- I only care about ASR models for English transcription
- It has to run without a dedicated GPU. My CPU is AMD Ryzen 5 7640U with 32GB of memory
- I don’t have any speech diarization needs (i.e., distinguishing different voices). I am the only speaker. I talk to the mic and I want my speech turned into text on the screen.
- No subscription services or cloud providers.
First, choose a local model
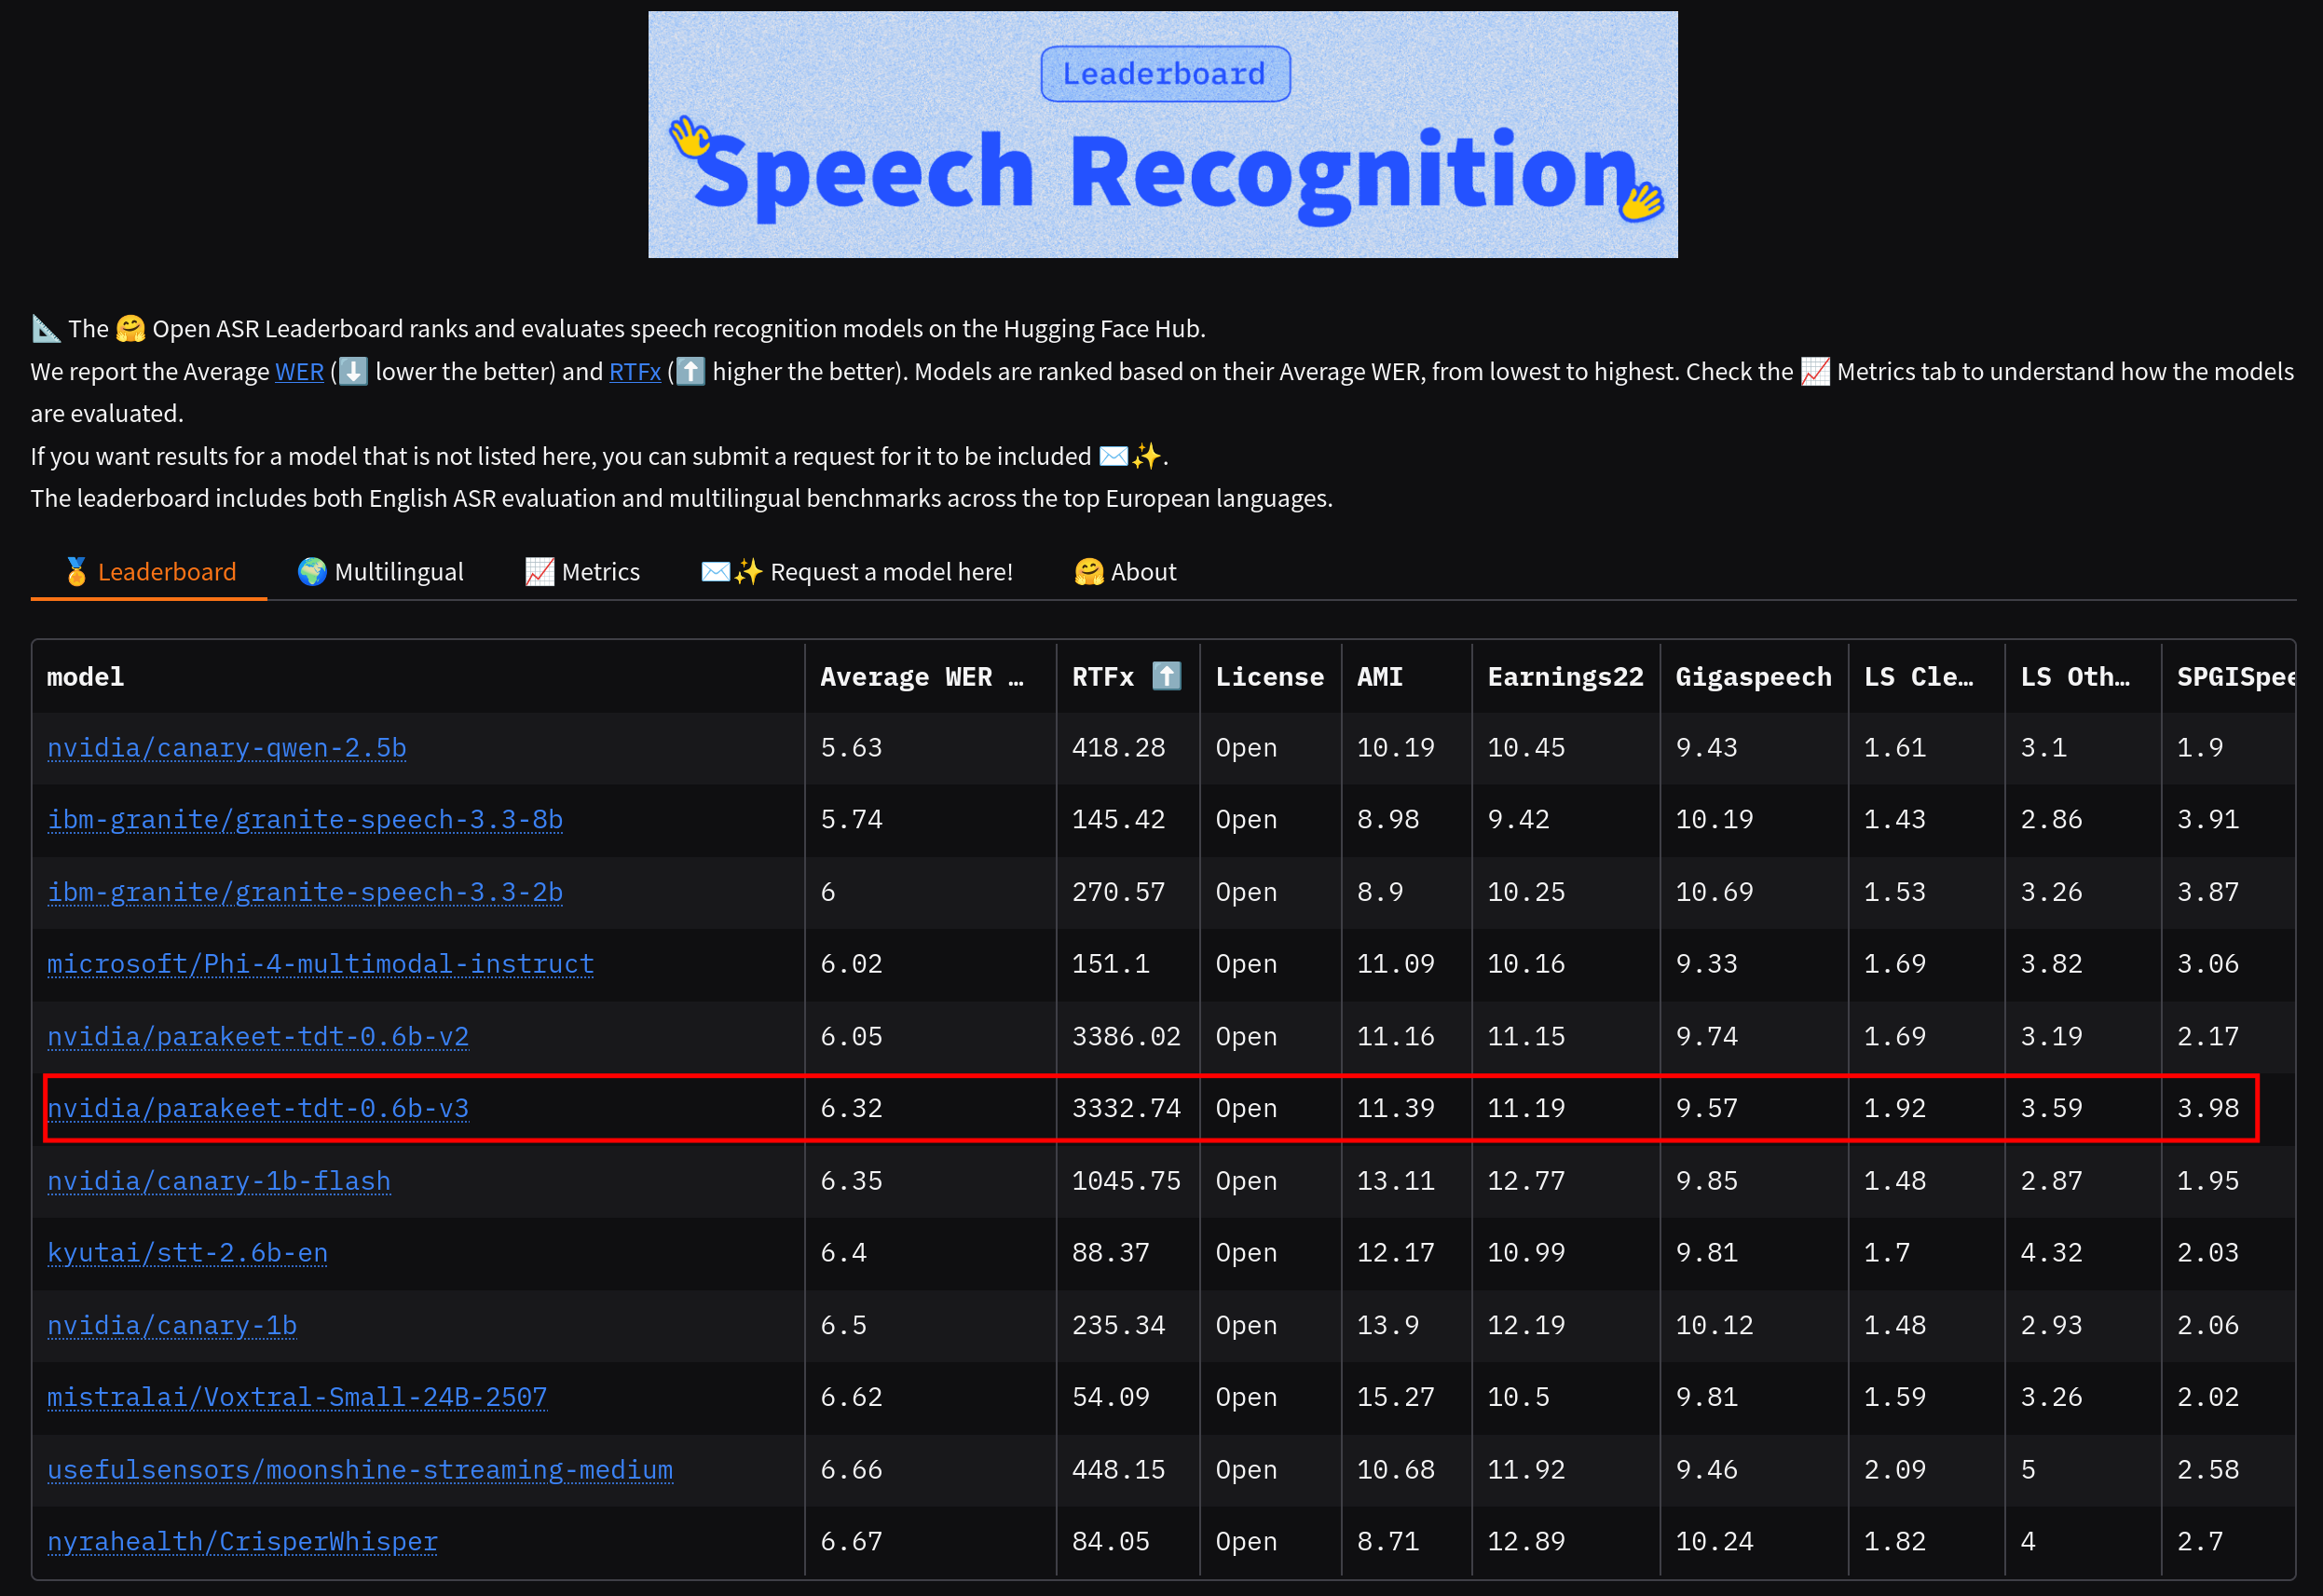
After trying different models, I think Parakeet V3 is the best in terms of speed and quality. I can run it localy comfortably without high latency (wait for a long time for the text to be transcribed). It’s not CPU intensive (i.e., the fan is not spinning like crazy). Being “good enough for me” is subjective, so I checked the Open ASR Leaderboard and glad that it confirmed my bias: Parakeet V3 is 6th on the list. Then I started looking for app with built-in support for Parakeet V3.
1. Handy
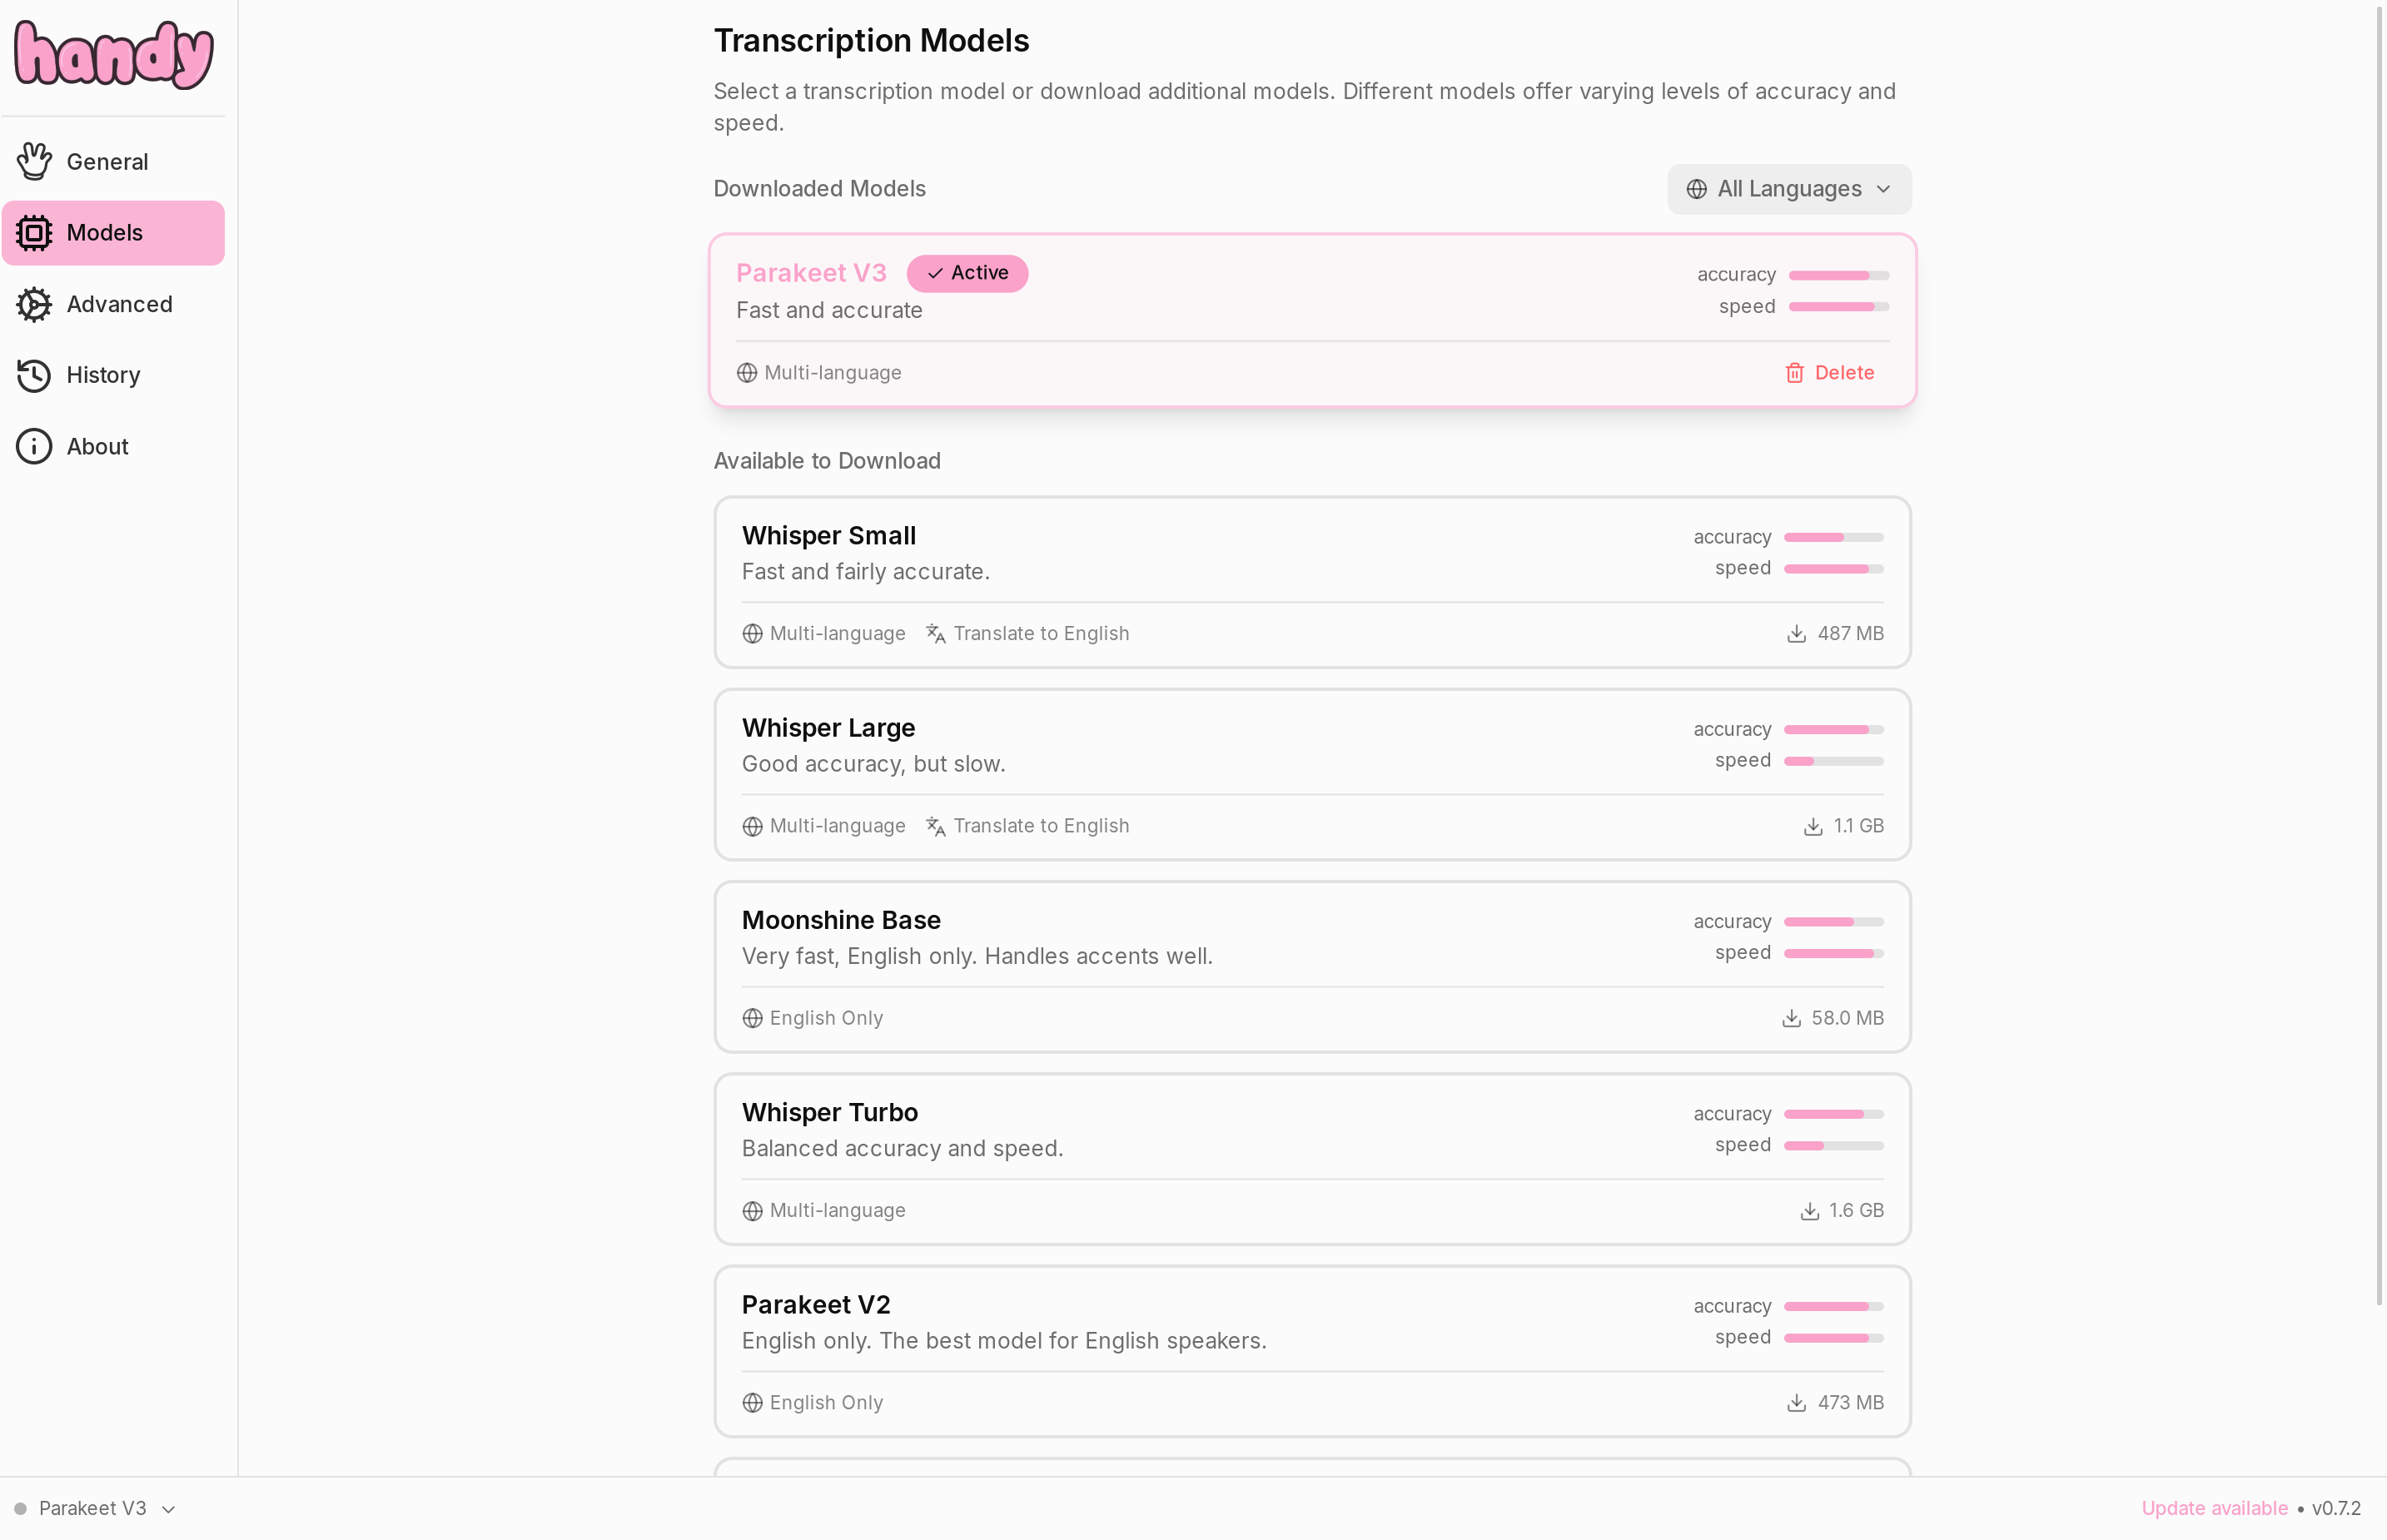
Handy is very handy (sorry!) for transcribing sentences (audio within a few minutes). I use it when I’m too lazy to type but not lazy enough to talk to a mic.
This app has some features over running the model directly:
- Maintain a list of history of past audio and output
- Audio feedback as Handy starts listening (bell sound when it starts listening)
- Visual feedback in the tray (icon changed when it’s listening)
Beyond the above niceties, the “killer” feature I really like is Unload Model set to never, which means that once I start using it, the model stays in the memory. Whenever I “Push to Talk”, I don’t need for it to load the model into memory again. This is very important because I don’t want to wait for a minute before I can talk, which would be a serious disruption to my workflow.
Hyprland Integration
As the doc suggests, we can set up some keybindings to trigger the starting and ending. When it’s finished processing it’ll directly type the output onto the screen. What’s impressive is that it supports Wayland out of the box (provided that you have installed wtype).
With the following, pressing the chord Super+a o will make Handy listen to your mic. Pressing the chord again will stop it.
bind =    $mod,          a,        submap,          mode_app

# mode_app
submap=mode_app

bind =    ,   o,        exec,           pkill -USR2 -n handy
bind =    ,   o,       submap,          reset

# Exit conditions
bind =    ,  escape,   submap,          reset

submap=reset
2. Parakeet TDT Transcription with ONNX Runtime
As you can tell from the name, it literally supports Parakeet V3. Supporting ONNX Runtime means that it helps greatly with inferencing on CPU.
Getting Started
As suggested in the README, we can use docker to install and run it:
git clone https://github.com/groxaxo/parakeet-tdt-0.6b-v3-fastapi-openai
cd parakeet-tdt-0.6b-v3-fastapi-openai
docker compose up parakeet-cpu -d
If I have recorded a long audio file in Audacity, I will navigate to the project dir and run it:
cd ~/repo/parakeet-tdt-0.6b-v3-fastapi-openai
docker-compose up parakeet-cpu -d && docker-compose logs -f
The web interface is then available at http://127.0.0.1:5092. I can drag and drop my audio file to have it transcribed. I download the result in SRT for easier editing.

Honorable Mentions
I have tried the following but they are not suitable for my use case. I mentioned them here to potentially alleviate your fear of missing out (i.e., what if there are better tools out there?)
1. onnx-asr
onnx-asr is a Python package / CLI that supports Parakeet V3.
Comparing to Handy: one big drawback is that it does not have the “Unload Model” feature. It could not replace Handy for short audio transcription because every time I use it, I need to wait at least a few minutes for it to load the model before transcribing. The latency is too high and I cannot stand it. Some people might like it because it frees up the memory, but given the model is not that big, the convenience of having it loaded in memory outweighs the memory footprint.
Comparing to Parakeet TDT Transcription with ONNX Runtime: It’s a very viable alternative. However, the latter supports SRT output out of the box and onnx-asr does not, but it should be possible to implement similar logic yourself.
2. nerd-dictation
Few years ago I used to use nerd-dictation. The CLI is very minimalistic, and I can pipe the output to ydotool to simulate typing on the screen on Wayland. It supports Vosk-Voice API which was good at that time but things have changed dramatically. Comparing to newer ASR models like Parakeet V3, the transcription quality is just not as good.
3. Whisper
Whisper from OpenAI has been the GOAT ever since it came out in 2022. There are a lot of app and tools surrounding the ecosystem. However, it was too resource intensive and has too high latency for my resource constraint. When I run it, the CPU would hit 100% and the fan would spin like crazy, and hence I did not consider it.
Conclusion
There are a lot of SAAS offering similar or exact features the above tools offer. Given the big privacy concerns, it’s much more dependable and safe to just use and run a local model.